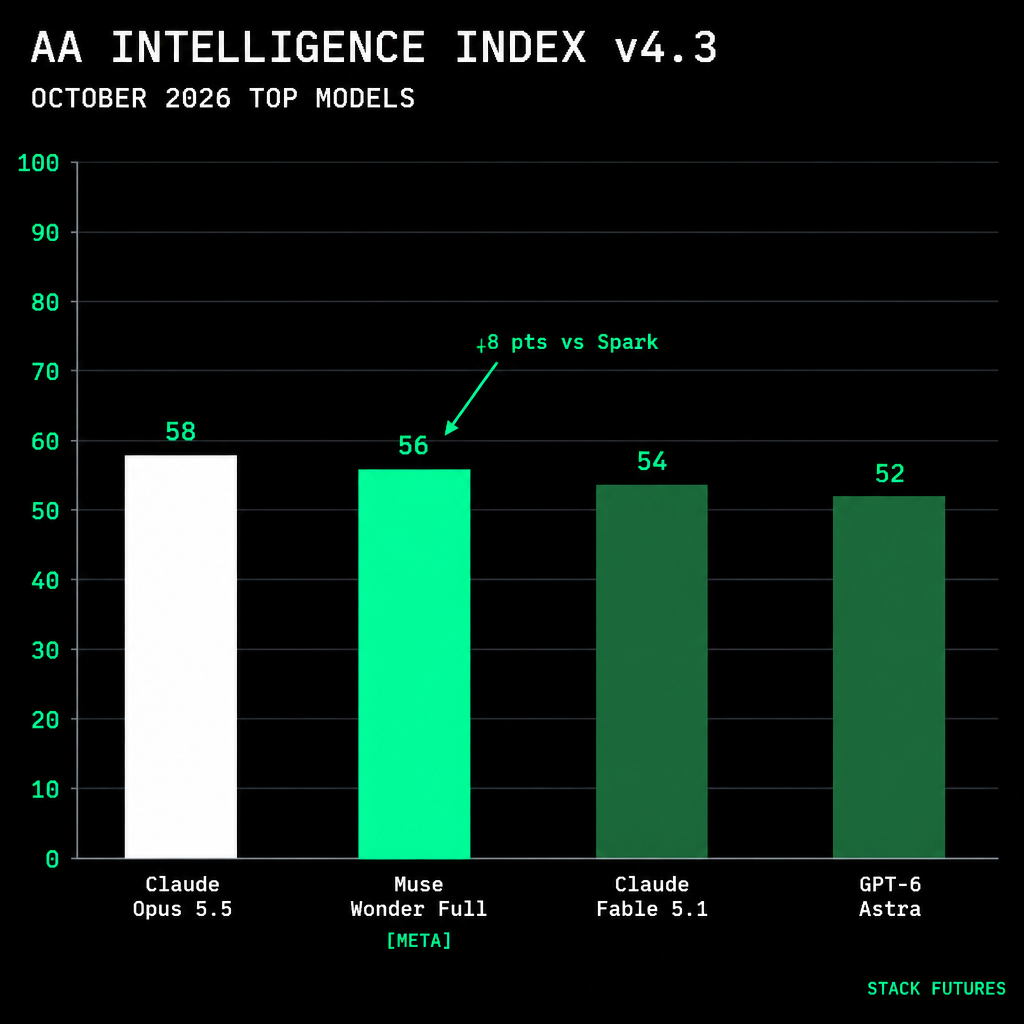
Muse Wonder Full Scores 56 on AA Intelligence Index, Ranks Second Behind Claude Opus 5.5
Three days after a benchmark-free launch, Muse Wonder Full gets its first independent score: 56 on the Artificial Analysis Intelligence Index v4.3, second globally behind Claude Opus 5.5 at 58 and ahead of Claude Fable 5.1 and GPT-6 Astra. Meta's 6-week jump from Muse Spark 1.3 at 48 is 8 index points.
Live Feed
GLM-5.3 Reaches 95.4% on SWE-bench Verified in Independent vals.ai Testing
vals.ai's neutral bash-only harness puts Z.ai's GLM-5.3 at 95.4% on SWE-bench Verified, placing it inside the top six globally alongside Claude Opus 5, DeepSeek V4 Pro, and GPT-5.6 Sol. It is the second Chinese lab model above 95% on an independent benchmark.
DeepSeek V4 Pro's Week-Long $0.21 Rate Was a Data Error, Not a Price Cut
Five consecutive observations of the DeAI Price Index confirm last week's $0.2088 input / $0.4176 output reading for DeepSeek V4 Pro on OpenRouter was anomalous. The corrected price — $0.9553 input, $1.9105 output — matches the September level exactly. No pricing event occurred.
Georgia Tech and Emory Commit $1.175 Billion to Build Atlanta Into a National AI Hub
Georgia Tech ($575M+) and Emory University ($600M) announce joint AI investments targeting advanced computing, healthcare, law, ethics, and workforce development. The combined $1.175B is the largest dual-university AI commitment in the US South.
Liquid AI LFM2.5-24B-A2B: 2B-Active MoE Tops Qwen3.6-35B on 5 of 8 Agent Benchmarks
Liquid AI releases the final and largest LFM2.5 model — a 24B-parameter sparse MoE with 2B active parameters, open-weight on Hugging Face with 131K context. It beats Qwen3.6-35B-A3B on five of eight agentic benchmarks while running on-device.
TypeSafe's System One Becomes Decision-Model Default in Six Weeks — OpenAI Sends a Fork
AWS, Upstage, Microsoft, Cloudflare, and Ollama all implemented TypeSafe's /v1/systemone endpoint within weeks of the category launching. OpenAI answered with its own Decisions API using different question-type names and no published schema, setting up a potential two-contract split.
Jon Peddie Research Values AI Processor Market at $588B as Inference Goes Rack-Scale
JPR's 203-page Q3 2026 report tracks 154 suppliers and 295 products across 10 processor families. The defining Q3 theme: inference is now a rack-level problem, with Nvidia Vera Rubin, AMD MI455X, and Google's dual-generation TPU push all optimizing for sustained agentic throughput over peak chip FLOPS.
Nvidia Commits $1 Billion to US Science Over Five Years, Extending Genesis Mission
Nvidia pledged $1 billion over five years to US scientific research capacity at a Washington event on October 8, 2026. The commitment covers quantum computing, healthcare, and energy security, and extends Nvidia's Genesis Mission partnership with the US Department of Energy, which already includes the largest DOE supercomputer at Argonne National Laboratory.
Arena Adds Eight Frontier Models to Search Arena Including GPT-6 Astra, Claude Fable 5.1, and Qwen 3.8 Max
Arena.ai expanded its Search Arena leaderboard on October 13 with eight frontier models including Claude Fable 5.1, GPT-6 Astra, GPT-6.1 Sol, Claude Opus 5.5, and Qwen 3.8 Max. Search Arena evaluates models on tasks where real-time web access is required, a different capability surface from the standard chat leaderboard.
LiveBench 2.0 Breaks Down the Frontier: Fable 5.1 Hits Perfect 100 on Browser Use, Gemini 4 Argon Leads Reasoning at 95.1
The updated LiveBench 2.0 leaderboard reveals no single frontier leader across all seven capability columns. Claude Fable 5.1 scores 100 on Browser Use but Gemini 4 Argon tops it on Reasoning and Data Analysis, while GPT-6.1 Sol undercuts every rival on cost at $0.734 per successful task.
Apple Research Turns Idle Macs Into a Distributed GPU Cloud for ML Inference
A new Apple Machine Learning Research paper introduces Minions, a system that aggregates idle Apple Silicon GPUs across macOS devices to run large-scale ML inference workloads without additional hardware purchases.
Gemini 4 Argon Opens to Everyone: 87% on Robotics ERQA, 1M Output Tokens, Intro at $2/M
Google lifts Fairwind access restrictions on Gemini 4 Argon on October 13, extending the model to all developers, enterprises, and consumers. New data: 87% on the Embodied Reasoning benchmark, a 1M unified token limit, and introductory pricing of $2/$10 per million tokens through November 30.
Character.ai Files Chapter 11, Begins Court-Supervised Asset Sale
Character.ai, the AI companion platform once pursued by both xAI and Meta, has initiated voluntary Chapter 11 bankruptcy proceedings to facilitate a court-supervised sale of the company and its assets.
AgentBeats Registry Opens Agent Benchmark Taxonomy to 13 Verticals Including DeFi, Healthcare, and Legal
AgentBeats.dev launches a benchmark registry and agent evaluation platform spanning 13 task categories, from coding and computer use to cybersecurity, finance, legal, and agent safety. The AgentX-AgentBeats competition adds a competitive layer on top of the open contribution model.
Claude Fable 5.1 Tops October LiveBench at 83.4, but GPT-6.1 Sol Delivers 98% of That at 12% of the Cost
Anthropic sweeps the October LiveBench top three with Fable 5.1, Opus 5.5 Thinking, and Fable 5. GPT-6.1 Sol sits 1.8 points back at $0.142 per successful task — against Fable 5.1's $1.212. The agentic coding column tells a separate story.